41 Wandering When Full
Exploration, Information, and Future Controllability
41.1 A controller cannot use an option it has never discovered
Chapter 40 ended with the cost of learning about other agents: which partner is reliable, what a local signal means, and how another person is likely to respond. An animal cannot recruit a particular partner it does not know exists or choose a refuge it has neither encountered nor inferred. Possibilities become available through direct experience, observation, communication, and inference. They need not all have been tried before they can guide action.
Chapter 15 already developed the adaptive argument. In “The adaptive problem: discovering future affordances,” exploration was the regulated body’s investment in future controllability. Its sections on state gates and sampling explained how bodily condition, novelty, arousal, and investigatory action make that investment possible. I retain that argument here. The additional problem is how the organism allocates sampling: which uncertainty is worth resolving, at what present cost, and over what future horizon?
The problem connects the preceding chapters. Chapter 37 asked how unlike expected outcomes enter one choice; Chapter 38 asked how selected information remains effective; Chapter 39 asked how anticipated consequences change the body. Each depends on what the organism knows, but information gathering does not have to finish before those processes begin. The current body and expected outcomes help determine what is sampled. What is learned changes value, attention, and the next action. Exploration, memory, valuation, and action selection continually alter one another.
The central requirement can be stated without installing an inner explorer:
A controller cannot use an option it has never discovered. Exploration changes what future control will be able to do.
The animal may acquire that information while pursuing an immediate need, while testing an uncertain alternative, while playing, or while roaming under conditions of satiety and safety. Those behaviors do not all arise from one drive. What joins them is that action changes the organism’s information about the world and therefore changes the set of policies available later.
41.2 Exploration is not one behavior
The most familiar formulation is the explore–exploit dilemma. To exploit is to select an option largely because experience already supports its value. To explore is to sample in a way that can change what is known about the available options. The terms describe the informational relation between action and choice. Exploitation can also produce learning; exploration gives sampling a role beyond simply taking the option currently estimated to be best. The distinction concerns the policy governing action, not whether information happens to arrive.
Several different policies can produce exploratory behavior. Directed exploration favors an uncertain option because information from that option could improve later decisions. The information has present value because it can alter a future choice. Random exploration, in the computational sense used here, makes choice less tightly determined by estimated reward, allowing less-favored alternatives to be sampled without an explicit uncertainty bonus. It need not give every option equal probability. Both can be adaptive. One biases choice toward information; the other loosens choice enough for alternatives to be sampled, preventing a controller from becoming permanently trapped by its current estimates.
Other behaviors overlap with these strategies but are not identical to them. Novelty seeking favors something because it has not been encountered before. Novelty often implies uncertainty, but the two can be separated. A familiar option may remain poorly understood, and a novel stimulus may reveal little that matters. Investigatory behavior includes orienting toward, approaching, sniffing, touching, or otherwise examining an object or agent. Patch leaving abandons a declining local source and accepts the cost of searching elsewhere. Need-directed search occurs when the current deficit cannot be corrected through a reliable known policy. Play can reveal the mechanical and social consequences of actions without an immediate practical payoff. Social sampling can identify partners, rivals, teachers, conventions, and sources of information.
Two terms need to be carried carefully from Unit 2. There, drive described the positive motivational force of investigation, with explicit qualifications about its varied mechanisms. Here, separating exploratory policies makes those qualifications concrete; it does not withdraw the claim that information can motivate action. Likewise, Unit 2 rejected random in the everyday sense of structureless movement. Computational random exploration can be regulated and can operate within highly organized behavior.
These distinctions prevent curiosity from becoming another invisible faculty with a single neural address. A mouse inspecting an unfamiliar object, a monkey preferring advance information about a reward, and a person selecting the less-known option in a bandit task all acquire information. They do not necessarily respond to the same variable, compute the same future benefit, or use the same circuitry.
Exploration can also be organized at several timescales. A momentary deviation may look like noise when viewed one choice at a time but become part of an effective search policy across many choices. Conversely, a systematic attraction to novelty can be locally orderly and globally wasteful. The category cannot be defined by whether behavior looks purposeful to an observer. It must be defined by what the sampling changes and how that information can influence later action.
Exploration is a family of information-acquiring control policies, not a unitary drive released whenever other drives fall silent.
41.3 Information can be worth acquiring now
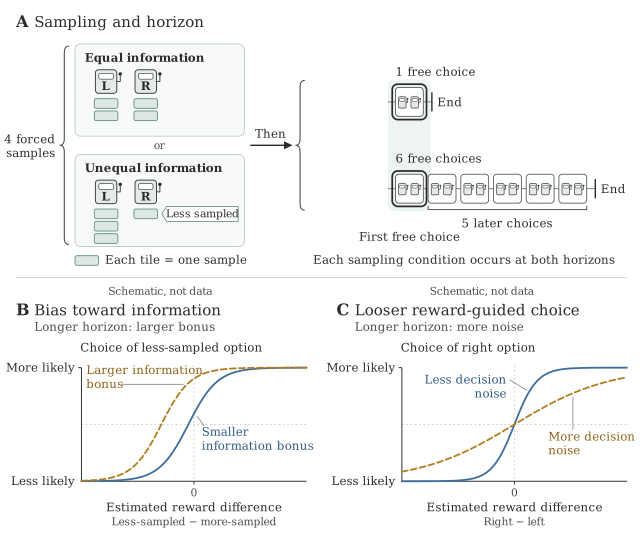
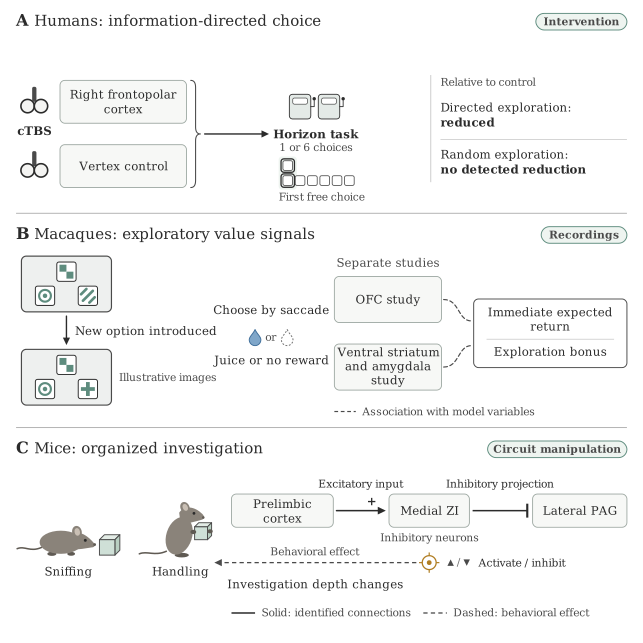
The Horizon task separates information from immediate payoff. Human participants first received four forced samples from two slot machines: either two from each, or three from one and one from the other. They then had one or six free choices. The critical comparison used the first free choice, before participants’ own sampling histories could diverge. The longer horizon created later opportunities to use information; it did not make either machine more immediately rewarding by design.
With unequal sampling, a longer horizon increased preference for the less-sampled option. With equal sampling, it increased choice variability relative to estimated reward. A model captured these changes as an information bonus and increased decision noise, respectively [@wilsonetal2014exploration]. The terms describe separable features of behavior. They do not establish that a participant consciously calculates a bonus or that every variable response is strategic.
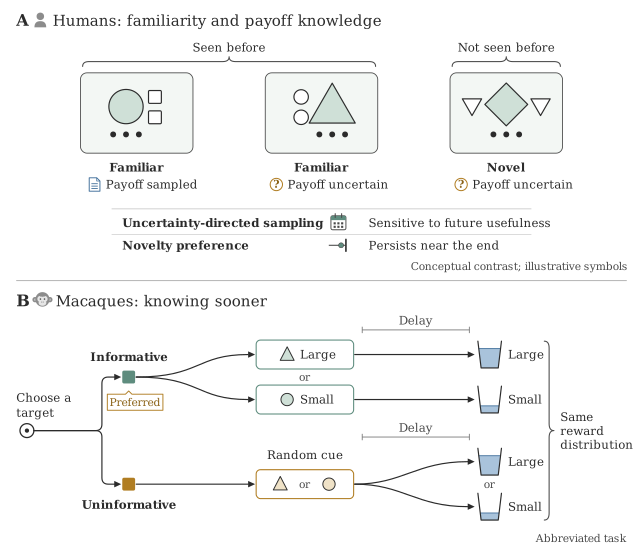
Information can also acquire value even when it cannot change the outcome. In an experiment with macaques, one cue revealed the size of an upcoming reward in advance, whereas another left the animal ignorant until the reward arrived. Choosing advance information did not change the reward distribution, yet the monkeys preferred it. Recorded midbrain dopamine neurons responded to expectations of both reward and information [@brombergmartinhikosaka2009information]. This separates information preference from the ability to improve that reward. It does not distinguish every possible source of the preference: anticipation and the learned attraction of predictive cues may contribute, and the recordings alone do not show that dopamine caused the choice.
Novelty adds another distinction. Cockburn and colleagues used a human task in which familiarity and knowledge of reward probability could be separated: an option could be familiar yet poorly known as a source of reward. Uncertainty-directed exploration was sensitive to whether the information could still be useful. Novelty produced a more persistent attraction. Their computational account combined optimistic initial reward expectations with a reduced influence of uncertainty for novel options [@cockburnetal2022novelty]. Novelty and uncertainty could therefore influence choice differently within this task; the fitted mechanisms should not be treated as uniquely established neural algorithms.
These findings replace the claim that exploration is simply a dumb pull toward the new. Some novelty-directed behavior may indeed be immediate and myopic. Random exploration can arise through increased variability rather than a represented information bonus. Directed exploration, however, depends on the relation between uncertainty and the choices still to come. Sensitivity to future usefulness does not require insight into an evolutionary purpose or an explicit verbal plan.
41.4 Wandering when full—and searching when hungry
The title returns to the “green zone” argument in Chapter 15. Physiological sufficiency and safety can make broad sampling affordable. A well-fed, well-watered, safe animal can afford actions that do not produce an immediate regulatory return. Failure is less costly. Time can be spent inspecting a new path, manipulating an object, playing with a conspecific, or learning the distribution of resources before any one resource becomes urgent. Wandering when full is exploration conducted with regulatory margin.
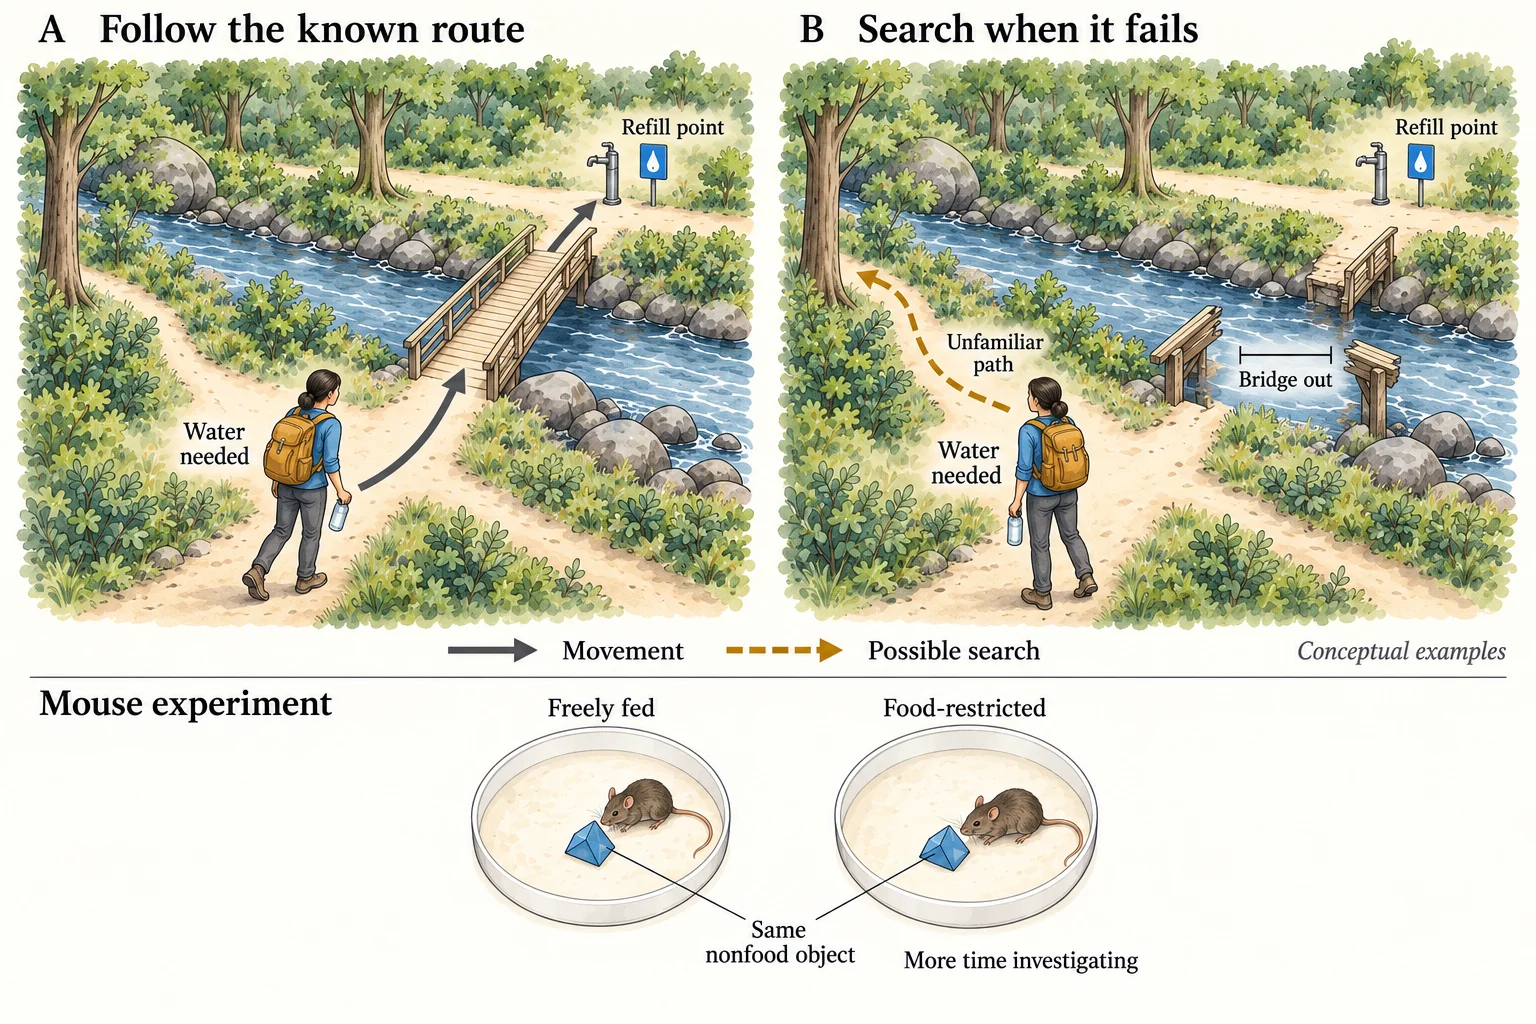
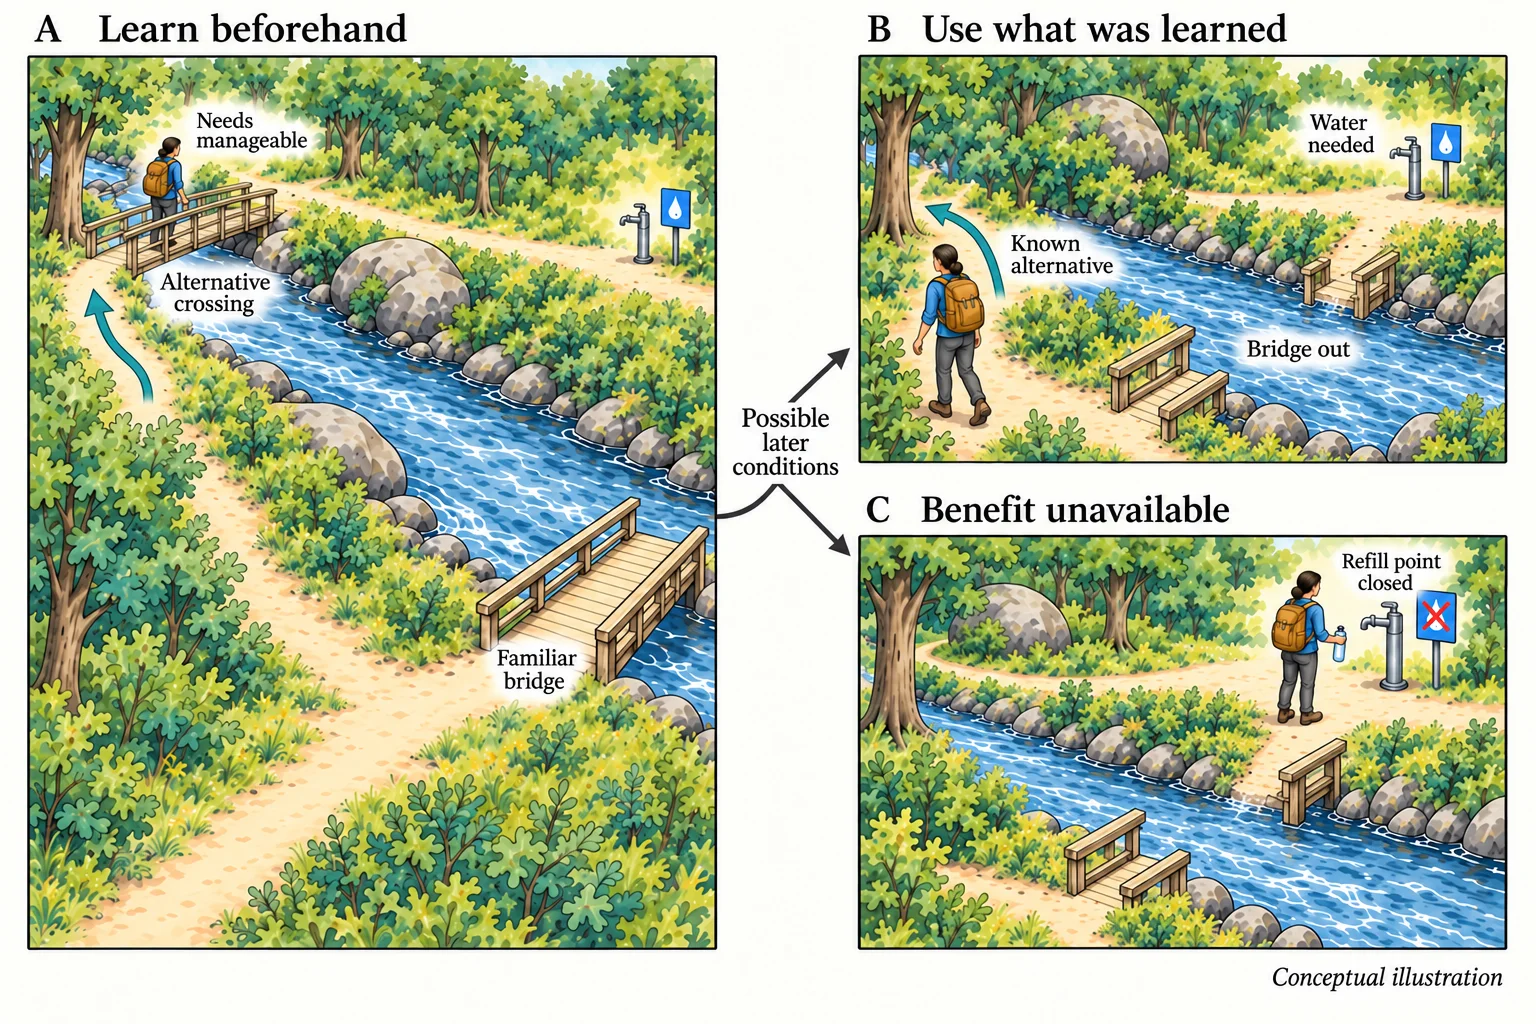
That margin matters because information has a price. Sampling consumes energy and time. It exposes the animal to hazards and may require abandoning a reliable source. When dehydration is severe and a known water source is available, unrelated exploration has a high opportunity cost. The familiar route deserves control because delay itself is dangerous.
But need does not switch exploration off. It changes what information is worth acquiring. When the familiar patch is exhausted, hunger makes search necessary. When a route to water is blocked, thirst raises the value of discovering another route. Threat can suppress broad sampling while making information about an escape path urgent. An animal in need may explore less widely and more purposefully, or it may accept risks that a sated animal would reject.
A mouse experiment makes the state dependence concrete. Kamath and colleagues compared food-restricted and freely fed mice investigating a novel, noncaloric object. Hungry mice spent more time investigating and showed less cautious positioning relative to the object. Dopamine measurements in the tail of the striatum showed reduced encounter-related signals in hunger; manipulations of those signals and hypothalamic AgRP neurons supported a causal contribution to the behavioral change [@kamathetal2025hunger]. The measured endpoints were investigation and risk-related behavior, not the later usefulness of what the mice learned.
The result is important precisely because the object did not contain food. Hunger changed how the animals sampled a potentially threatening novelty even in the absence of a caloric reward. It did not merely point locomotion toward a known meal. The experiment does not establish one universal effect of food deprivation across species and settings. It establishes the more important principle: bodily need can increase exploration as well as narrow it.
The state gates summarized in Figure 15.2 should therefore be read as context dependent influences. Three control situations clarify the distinction:
| Current condition | Informational problem | Likely consequence for sampling |
|---|---|---|
| Urgent need; reliable known solution | Little useful uncertainty about the next action | Favor the known route; delay is costly |
| Urgent need; familiar solution fails | Uncertainty obstructs correction | Search can become urgent and focused |
| Needs manageable; setting sufficiently safe | No single immediate deficit dictates the question | Broader sampling becomes affordable |
These are control situations, not universal laws of behavior. Satiety is not an on-switch for curiosity. Hunger is not an off-switch. Bodily state changes the target, breadth, risk tolerance, and useful time horizon of information acquisition.
The same logic applies beyond hunger. Fatigue changes the cost of a distant route. Thermal stress changes the value of shade and the danger of delay. Injury changes which actions are feasible. Social isolation can raise the value of information about potential partners while social threat raises the cost of approaching them. The body does not supply exploration with a generic amount of motivation. It changes the consequences of sampling this option, in this place, now.
Bodily state changes the price and the likely use of information.
41.5 Exploration changes what the controller knows
The immediate product of exploration is not always reward. Sometimes it is a change in what the animal can later infer.
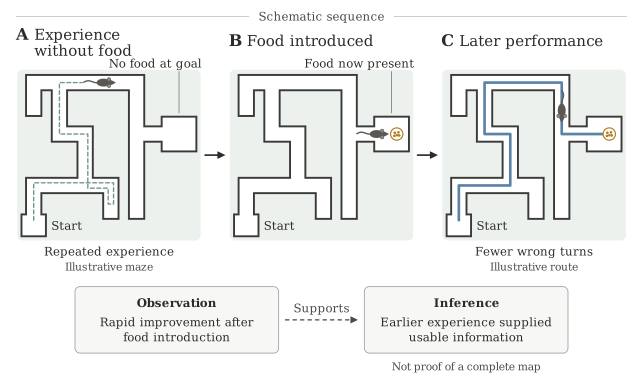
The classic latent-learning experiments made this distinction visible. Tolman and Honzik allowed rats to traverse a maze without food reward and later introduced food at the goal. Performance then improved rapidly, indicating that experience acquired before reward had altered what the animals could do once an incentive made that knowledge useful [@tolmanhonzik1930latent]. The result helped establish the distinction between acquisition and performance. Improved performance after food was introduced was evidence that earlier unrewarded maze experience mattered; it was not, by itself, proof of a complete spatial map or of learning without every possible reinforcing consequence. What an animal has learned cannot be read directly from its current performance.
The “Effectors: movement, sampling, arousal, and model updating” section of Chapter 15 already linked sampling movements to changes in prediction. Here the important distinction is what can be learned. Exploration can change several kinds of knowledge. It can reveal where resources and hazards are located, which landmarks predict a turn, and which routes remain available when the shortest path is blocked. It can reveal transition structure: what state is likely to follow an action, where a corridor leads, or how a tool changes an object. It can reveal volatility: whether the environment is stable enough for an old estimate to remain useful. It can also reveal affordances that are specific to the body. A gap that can be crossed when rested may not be crossable when injured or carrying a load.
The social world enlarges the same problem. Exploration identifies more than mates or competitors. It reveals who provides reliable information, who reciprocates, who dominates access to a resource, which signals are trusted, and which local rules govern exchange. Direct interaction, observation, and testimony can all supply this knowledge. As the preceding chapter emphasized, another person’s welfare can matter even when that person will never respond; predicting a response is only one use of social information.
Exploration also changes estimates of ignorance. Sampling may reveal that a familiar option is more variable than it appeared, that a supposedly safe route has become unreliable, or that the animal’s model omitted an entire class of possibilities. The most important discovery is sometimes not a new resource but the inadequacy of the current policy.
These changes do not remain in an isolated exploration system. Hippocampal and cortical memory systems preserve relational, spatial, episodic, semantic, and social structure. Value-learning systems update expected consequences. Sensory and motor systems become more efficient at recognizing and acting on familiar features. The newly acquired information changes later attention, valuation, route selection, and imagination.
This is the bridge to the next unit. The present chapter asks why and when an organism samples beyond its current policy. The next unit asks how experience becomes the maps and memories from which routes, scenes, and possible futures are later constructed.
41.6 Stability and exploration are complementary control states
Chapter 38 described the problem of keeping a valid goal effective across distraction while remaining able to update when evidence changes the situation. Exploration is not the opposite of that capacity. It is one of the ways updating occurs.
A novel event can be an irrelevant distractor, evidence that the current policy has failed, or an opportunity worth sampling. Those cases cannot be classified from novelty alone. A flash in the periphery should usually not pull a thirsty animal off a reliable route to water. A newly fallen tree blocking that route must reorganize behavior. The controller has to determine whether the present event changes the problem.
Directed exploration can itself require strong goal maintenance. A scientist who systematically varies one condition, a child testing how a mechanism works, or an animal checking several branches of a route is not surrendering to capture. Each must resist immediate rewards and unrelated novelty long enough to complete an information-gathering policy. Random exploration likewise need not be uncontrolled distraction. Increasing variability can be a regulated response to uncertainty or environmental change.
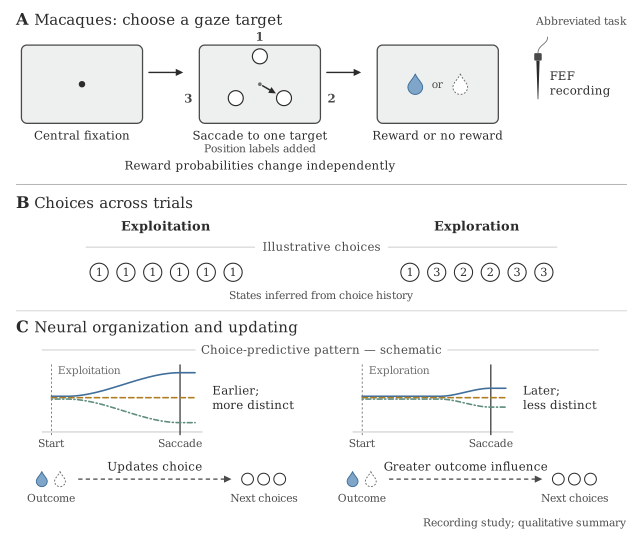
Recordings from monkeys show what such a change of control state can look like. Ebitz and colleagues recorded from frontal eye field neurons while animals shifted between exploiting a reliably rewarded target and exploring alternatives. During exploration, spatially selective choice-predictive activity weakened and population dynamics associated with the chosen target emerged later. At the same time, behavior and neural activity became more sensitive to new reward outcomes [@ebitzetal2018exploration]. The established sensorimotor mapping loosened while learning increased.
That reconfiguration is not simply a failure of prefrontal control. It is a change in what control is doing. A stable mapping is useful when the environment is reliable. The same stability becomes a liability after reward contingencies change. In monkeys performing reversal learning, environmental volatility increased the influence of recent outcomes and altered outcome- and choice-related activity in orbitofrontal and dorsolateral prefrontal cortex [@massietal2018volatility]. These recordings support a change in how prefrontal populations use recent evidence. They do not establish that persistence and flexibility have identical mechanisms. The useful connection to Chapter 38 is that maintaining a policy and revising it can depend on changes within interacting circuits, rather than a contest between a stable executive and an external source of disruption.
The relationship can therefore be stated more precisely than a contest between dorsolateral persistence and exploratory capture:
Adaptive control must neither surrender to every novelty nor preserve a policy after the world that justified it has changed.
Exploration can involve relaxation, variation, or replacement of a current policy. Whether that change is adaptive depends on the return from information relative to its cost; exploratory behavior does not guarantee that the tradeoff has been solved well. Exploitation protects a policy whose estimated consequences remain good enough. Neither state is intrinsically superior. The problem is the transition between them.
41.7 The machinery is distributed and evolutionarily old
The anatomical setting is already established. Section 36.3 located the frontal territories; Section 36.4 described bodily and contextual influences; Section 36.5 traced their participation in cortical, basal-ganglia, thalamic, and neuromodulatory interactions. Exploration asks a particular question of that architecture: how does an alternative gain enough influence to be sampled, and how does the result change subsequent control? The experiments below identify different contributions to that process.
41.7.1 Frontal systems keep alternatives and horizons effective
Human imaging drew attention to the frontal pole. In a changing gambling task, choices classified by a learning model as exploratory were associated with greater frontopolar and intraparietal activity. Striatal and ventromedial prefrontal signals were more closely related to estimated reward value [@dawetal2006exploration]. Another experiment found that lateral frontopolar activity tracked evidence favoring a foregone alternative and changed its coupling with other regions when participants switched [@boorman2009alternatives].
These findings identify contributions, not an exploration center. A causal test was more selective. Compared with stimulation at a control site, continuous theta-burst stimulation over right frontopolar cortex reduced directed exploration in the Horizon task without a detectable reduction in random exploration [@zajkowski2017frontopolar]. The intervention supports a contribution to information-directed choice in this task. It neither isolates every affected connection nor shows that this region alone represents the horizon or computes information value.
Medial frontal cortex enters when continuing a current course must be compared with searching elsewhere. In a human foraging task, dorsal anterior cingulate activity tracked variables related to leaving a current option and searching an environment whose average richness varied [@kollingetal2012foraging]. A subsequent experiment that separated those variables found that activity attributed to foraging value was better explained by choice difficulty [@shenhavetal2014difficulty]. The disagreement is instructive. The task recruits medial frontal systems, but the variable explaining their measured activity depends on how the alternatives and difficulty are separated. This contrast does not settle a universal computation for the region. As the overview noted, anatomical territory often called dACC in this literature also overlaps labels such as anterior midcingulate cortex.
Taken together with the maintenance evidence, these findings suggest how rules, alternatives, recent outcomes, and opportunities for later choice can remain effective within frontal networks. The control interpretation is that different information gains influence as the task changes. It does not assign each variable to one territory or require frontal systems simply to suppress novelty.
41.7.2 Value, learning, and action selection
Exploration already contains a value problem. The organism must compare immediate reward with the possible benefit of information, subtract energetic and opportunity costs, and incorporate current bodily state. Orbital and ventromedial prefrontal systems contribute state- and outcome-specific value signals; they do not wait for an exploration system to deliver a completed map.
In monkeys choosing among familiar and newly introduced options, orbitofrontal recordings contained signals related to chosen stimulus identity, outcomes, and model-derived values, including an exploration bonus: the additional prospective return assigned to sampling [@costaaverbeck2020orbitofrontal]. Ventral striatum and amygdala also represented different aspects of immediate exploitative value and future exploratory value [@costaetal2019subcortical]. These are correlations with variables from an explicit decision model, not direct measurements of a consciously anticipated benefit. They place exploratory value within systems already involved in learning and outcome evaluation; they do not establish the causal necessity of each recorded signal.
Dopamine makes the point especially clearly because its contribution changes with projection, target, state, and task. The macaque information experiment showed dopamine signals related to advance information about reward [@brombergmartinhikosaka2009information]. Systemic dopamine-transporter blockade increased monkeys’ preference for newly introduced options. A fitted learning model attributed the change to higher initial value estimates, without a detectable general increase in choice noise or learning rate [@costaetal2014dopamine]. In hungry mice, by contrast, increased investigation of a novel object depended on suppressed dopamine signaling in the tail of the striatum [@kamathetal2025hunger]. There is no single dopamine signal that makes the unknown attractive. Through anatomically distinct circuits, dopamine systems can alter learning, salience, risk assessment, action vigor, and the value assigned to novelty.
Recordings from a basal-ganglia output nucleus add another level of evidence. During associative learning in monkeys, lower firing in a subset of internal globus pallidus (GPi) neurons predicted early exploratory responses, whereas higher firing accompanied later exploitation of the learned response [@shethetal2011basalganglia]. The association is compatible with changing constraints on action, but it does not show that the recorded firing change caused exploration. Section 36.5 placed GPi within the broader action-selection architecture. Here the result connects that output level to exploratory behavior without making GPi an exploration module.
Baseline and task-evoked pupil diameter have also changed as participants moved between sustained task engagement and lower-utility states interpreted within an explore–exploit framework [@gilzenratetal2010pupil]. Such findings are consistent with a contribution from neuromodulatory systems, including locus coeruleus–noradrenergic projections, that can alter neural gain and the stability of ongoing processing. Pupil diameter is influenced by many processes and is not a direct assay of one nucleus. The important point is that exploration involves changes in the operating state of distributed circuits, not only a comparison made at the frontal pole.
41.7.3 Older circuits investigate a world
The earlier account in Chapter 15, especially “Hypothalamic circuits: state gates, novelty gates, and action release,” already explained the investigatory machinery summarized in Figure 15.1. The important comparison here is between organized investigation and the experimental directed exploration defined by an uncertainty bonus. They are related questions, but the same adjective does not make the behaviors equivalent.
In mice, manipulations of inhibitory medial zona incerta (ZI) neurons altered the depth and duration of investigation; the study implicated prelimbic input and an inhibitory ZI projection to lateral periaqueductal gray (PAG) [@ahmadlouetal2021investigatory]. In macaques, a temporal-cortex–ZI pathway contributed to gaze choices that provided access to novel visual stimuli [@ogasawaraetal2022novelty]. These are causal findings about specified forms of sampling. Neither experiment asked whether an animal assigned a larger information bonus when more future choices remained.
ZI is usually classified as subthalamic or prethalamic, rather than as a hypothalamic nucleus. Its inclusion preserves Unit 2’s account of neighboring diencephalic and brainstem systems participating in control. The mouse prelimbic–ZI–PAG findings and macaque temporal–ZI findings should remain separate experiments, not be joined into an untested human pathway. Together they show that investigation is implemented through cortical–subcortical interactions and does not require a uniquely human frontal territory.
Human exploration extends across longer plans, language, and socially transmitted knowledge. Frontal elaboration contributes within a wider architecture that includes memory, perception, language, and learned cultural practices; these capacities cannot be attributed to the frontal pole alone. A person can explore a hypothesis, a legal precedent, an archive, or another person’s testimony without physically roaming a landscape. The ancient operation—sample beyond the currently favored policy—has been extended across language, institutions, and imagined futures.
41.8 Exploration as an allostatic investment
I return now to the interpretation introduced in Unit 2. Exploration can be understood as an allostatic investment: present activity can improve regulation of later demands. Calling it a drive emphasized its motivational force. Calling it an investment brings its costs, possible returns, and failures into view. These are organism-level descriptions of the same problem, not claims about a separate physiological controller.
Chapter 37 already treated value as a relation between predicted consequences and a body in a present and anticipated state. Exploration adds the possibility that an action changes the information on which later predictions and choices depend.
Exploration becomes allostatic when present sampling improves the organism’s capacity to regulate later. The organism pays now in energy, time, exposure, and foregone reward. The return can be a shorter route to water, an alternative refuge, a more accurate estimate of danger, a new action–outcome relation, a reliable partner, or evidence that the current policy is obsolete.
As in Chapter 15, I use future controllability for that possible return. This is a functional organizing concept, not a claim that the brain defends one measured scalar or that we have established controllability in the strict mathematical sense. It means the number, accessibility, reliability, and estimated consequences of the actions through which a later disturbance can be corrected. An animal with one known route to water is vulnerable to one obstruction. An animal that has sampled several routes, learned their costs, and discovered another source possesses greater future controllability even while it is not thirsty.
The investment has identifiable boundary conditions. Information is most useful when the organism is likely to encounter the environment again, can retain or generalize what it learns, and faces enough stability for the information to remain valid. Its instrumental return shrinks when there is no later opportunity to use or generalize the information, when change makes it obsolete before use, or when present risk is catastrophic. Changing environments can also make renewed sampling more valuable; the critical relation is between the pace of change and the pace at which information can be acquired and used. Advance information may still be preferred even when it cannot improve the outcome, as the macaque experiment showed. Novelty can also be engineered to capture attention without improving later control. An exploratory system can waste time, enter a trap, or continue sampling after the useful uncertainty has been resolved.
These failures do not weaken the functional claim. They define it. Selection does not produce a homunculus that knows why information will matter. It produces state-sensitive mechanisms that vary behavior, investigate novelty, value uncertainty, and learn from the result. The evolutionary proposal is that such mechanisms can be favored when their effects on later survival and reproduction outweigh their present costs. The experiments reviewed here test parts of that account; none by itself demonstrates that evolutionary history. The animal need not represent that evolutionary reason. Directed exploration can still represent the local fact that information gained now will improve choices later.
Exploration is an allostatic investment when present information acquisition enlarges the set of reliable actions available to future regulation.
This formulation carries the Unit 2 argument forward. Wandering when full can stock knowledge before need becomes urgent. The investment is implemented by several policies and many interacting circuits. Its success depends on what is learned and on whether that knowledge can later become effective in action.
41.9 Coda: a represented future still has to be mobilized
Exploration can enlarge what the organism knows how to do. The remaining question is whether an available, potentially valuable goal recruits action. A person may describe a sensible plan and retain the capacities needed to carry it out, yet fail to begin without external prompting.
That gap does not lie after a completed sequence of discovery, valuation, bodily preparation, and maintenance. Those influences remain active together. Tomorrow Never Comes asks how their recurrent interaction mobilizes effort, initiates action, and sustains engagement—and how these contributions can come apart.
Established findings. Human tasks distinguish sensitivity to information from changes in reward-guided choice variability, and show that both can depend on future opportunities to choose. Novelty preference, advance-information preference, and organized investigation are experimentally separable. In the cited mouse task, hunger increased investigation of a nonfood object through changes involving AgRP activity and tail-striatal dopamine. Frontopolar stimulation, primate recordings, and investigatory-circuit manipulations provide different kinds of evidence about different behaviors; they do not identify a single exploration system.
Working synthesis. Exploration can function as an allostatic investment in future controllability. By paying present costs to acquire information, an organism can enlarge the number, accessibility, and reliability of the actions through which later disturbances may be corrected. This is the organism-level functional proposal developed in Unit 2, now refined by distinctions among policies, horizons, and costs. It does not imply that every exploratory act improves future control, or that all information preference has an instrumental benefit.
Open questions. It remains uncertain how bodily states redistribute different forms of exploration across natural settings; how novelty, uncertainty, volatility, risk, and future horizon are integrated; how directed and random strategies interact during extended behavior; and how information acquired through physical, social, and symbolic exploration is consolidated into maps and models. The neuromodulatory mechanisms are also unresolved. Dopamine and noradrenaline act through heterogeneous projections, and the same transmitter can have different effects in different targets and states. Finally, an information-acquiring policy can improve future control or become a route for distraction, compulsion, and engineered capture. Explaining that boundary is part of explaining exploration itself.